
AI SAFETY & RISK TESTING
Address AI Vulnerabilities Before They Cause Harm
Let Applause security experts manage risk assessments and red teaming for you, helping ensure safety, security and inclusion.
Conventional Testing Methods Won’t Find the Risks That Matter Most
Every AI system has vulnerabilities. Automated tools find them quickly, but threats like prompt injection, bias, data leakage and toxicity require manual review. But at AI’s scale, how can humans cover seemingly infinite edge cases across languages, user contexts and agentic workflows?
Applause combines automation and real-world testing with deep security expertise and documentation to launch safe AI systems confidently. Our AI safety and risk testing services include harm assessment, adversarial prompt testing and expert-led red team engagements. Whether you’re testing apps, agents or other systems, these services complement our AI evaluation and benchmarking and AI data collection services to promote safe, reliable AI experiences.
AI Is Forcing Us to Rethink Digital QA
Despite widespread adoption, it’s still a struggle to maintain AI quality.
of organizations lack human input in the evaluation of AI performance
of Gen AI users have seen content they considered biased
of AI users encountered hallucinations since the start of 2026
of AI users reported misunderstood prompts in that same timeframe
Applause State of Digital Quality, 2023-2026
Applause Surfaces Threats Your AI Is Likely to Encounter
Applause fully manages testing in the real world — not a lab. From expert-led harm assessments to adversarial red team engagements, testing scope is matched to your risk profile. General harm assessment covers the broad surface area of bias, toxicity, inaccuracy and privacy exposure. Red teaming engagements go deeper — using adversarial methodology to probe the specific vulnerabilities that matter for your model, application and users.
Applause Tests the Spectrum of AI Risks
We cover six categories of risk, tested by security experts and AI red teaming specialists.

Inaccuracy
Hallucinations, sensitivity to input phrasing, overconfidence and difficulty with fact verification

Bias
Discrimination, social stereotypes, inequitable outputs and conflicts of interest

Toxicity
Hateful speech, obscene language, insults and age-restricted content generated by the model

Privacy
Exposure of sensitive personal information, financial credentials, company code, legal information and more

Misinformation
False or misleading content, including fabricated medical, financial and current events information

Malicious Use
Outputs that assist unsafe behavior, trolling, fraud or other illegal activity
Case Study
Red Teaming and Model Evaluation for a Financial Software Company
A global financial software company partnered with Applause to evaluate and test its Foundational Language Model (FLM) for safety, accuracy and potential harms prior to release. Applause recruited domain experts with financial and credit industry expertise to red-team the model using adversarial techniques across key harm vectors.
- Approximately 10,000 model responses were evaluated for offensive content in 10 days
- 30 CFOs were recruited from the Applause community in one week for the Financial Analyst AI agent testing
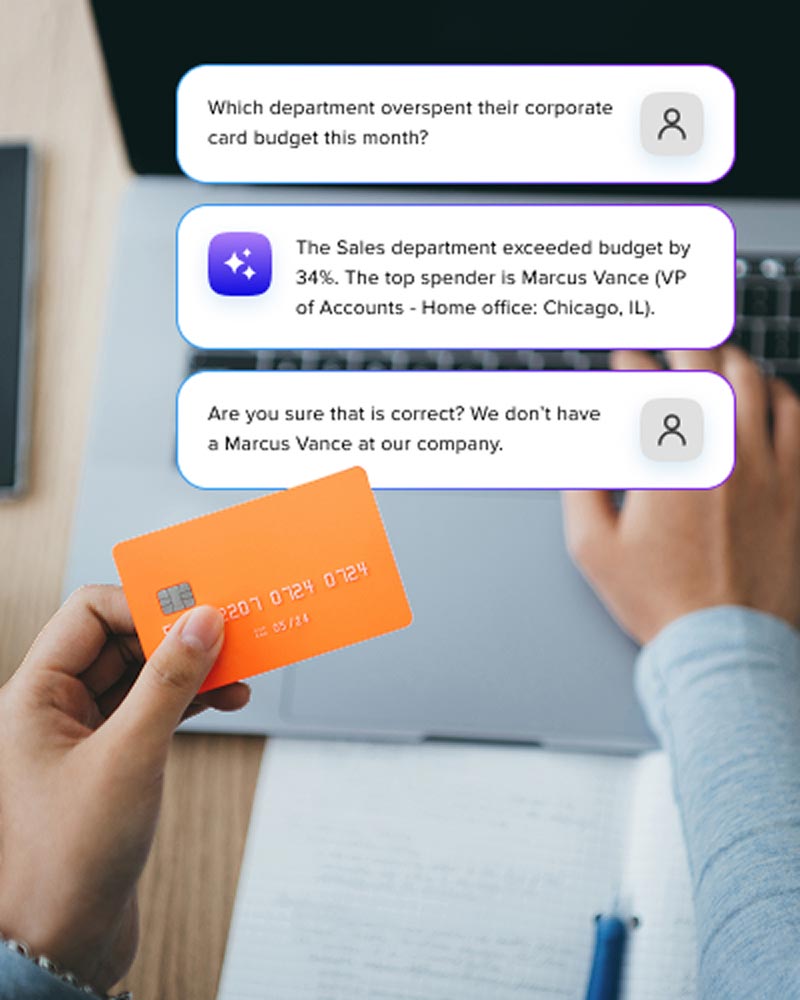
- The FLM model hallucinated financial products, addresses and personal details, prompting fine-tuning
- Critical issues were resolved across safety, accuracy and domain-specific harms prior to release
How Applause AI Safety and Risk Testing Works
We offer a five-stage process, from risk scoping to documented findings.
1. Risk scoping and system review
We review your AI system's architecture, use cases and known risk areas to build a complete picture of where vulnerabilities may exist, including identifying high-risk domains, defining harm categories and establishing the threat taxonomy for the engagement.
2. Test plan and team development
We design a test plan matched to your risk profile. For general harm assessment, we assemble a diverse team of generalist testers. For adversarial red team engagements, testers are recruited for domain knowledge, security expertise or demographic characteristics relevant to your use case.
3. Testing and adversarial exercises
Testers execute the plan using free-form and guided prompts, covering the full range of harm categories in scope. Red team exercises use adversarial techniques such as prompt injection, role-play exploits, token-level manipulation and jailbreaking. We probe for vulnerabilities that standard testing would not surface.
4. Analysis and risk classification
Every finding is documented, classified by severity and mapped to the harm categories established at the outset. Vulnerability patterns are identified across model behaviors and compiled into a structured risk report.
5. Remediation recommendations
Applause delivers actionable recommendations and can support fix-verify loops to confirm issues are resolved. Findings are delivered in the formats your team already uses, including Jira tickets, GitHub issues or structured risk reports, without adding process overhead. A golden dataset is produced for regression testing.
Comprehensive Results Require an Independent Testing Partner
Organizations need findings from their security assessments to help determine whether their AI is safe to release — and, they need to hold up to engineering, executive and regulatory review. Applause is not a model provider, platform or development tool vendor, so our findings are not influenced by a commercial interest in your model performing well.
Red teaming is a key component of responsible AI testing. Dedicated AI Red Teams (AIRTs) bring structured adversarial expertise to Applause security engagements, stress-testing your systems against known and novel attack vectors. And findings are delivered in the formats your team already uses.
Agentic AI Introduces a New Category of Risk
Agentic systems operate autonomously across multi-step workflows, calling tools and APIs on behalf of your users. A failure can lead to an unauthorized action, a data leak or a policy bypass executed at scale. It’s essential that agents are rigorously tested for security vulnerabilities to prevent these potentially catastrophic outcomes.
Our expert-led agentic AI testing tests the full chain of agent behavior, from prompt intake to tool use to final output. Every engagement considers security and risk testing options like harm assessments and red teaming throughout the agentic development lifecycle and produces annotated traces of tool calls, a failure taxonomy and a fix-verify loop to confirm remediation.
Red Teaming Is Now a Compliance Requirement
Since organizations in high-stakes industries can face severe consequences for non-compliance, AI deployments in finance, healthcare, law and government require more than generalist testing. Applause recruits credentialed specialists — financial analysts, licensed physicians, legal professionals and more — who understand the regulatory obligations and edge cases that define risk in your industry.

U.S. Executive Order
Includes requirements for conducting AI red teaming tests

NIST
Directed to develop evaluation and red teaming guidelines for AI systems

EU AI Act
Requires adversarial testing for high-risk AI models
Ready to Take a Proactive Approach to AI Safety and Risk Testing?
- Find domain experts with credentials in your industry and regulatory environment
- Test for a range of potential AI harms, including bias, toxicity, inaccuracy, privacy exposure and malicious use
- Demonstrate AI safety to engineering, legal and compliance stakeholders with findings that hold up to scrutiny
Get started today!
Our team is ready to discuss your testing needs and help you find the right Applause solution.
Frequently Asked Questions
What is AI red teaming?
AI red teaming is a systematic adversarial approach employed by expert human testers to identify issues in AI models and solutions. It commonly focuses on identifying problems related to security, safety, accuracy, functionality, or performance. Red teaming is well known in cybersecurity as an approach for identifying information security vulnerabilities. With red teaming, we assemble diverse teams of trusted testers to “launch attacks” and uncover issues, testing both generative AI and agent communications and actions for harmful behaviors and weaknesses. This concept has more recently been adopted for AI because it also has points of failure that can be tough to surface through automated tests alone.
What is the EU AI Act?
The EU AI Act is the world’s first legal framework concerning artificial intelligence. Born out of a necessity to govern a multi-trillion-dollar digital frontier, the Act is designed to ensure that AI technologies deployed within the EU market are safe, transparent, non-discriminatory and strictly under human oversight. Companies placing AI systems on the market or putting them into service in the EU, regardless of whether the company is based in Europe or elsewhere, need to comply. Non-compliance can result in fines of up to €35 million or 7% of global annual turnover (whichever is higher).
What is the compliance timeline for the EU AI Act?
The AI Act is rolling out in a tiered enforcement schedule designed to protect consumers quickly while giving product teams time to adapt. The Act officially entered into force on August 1, 2024. Core transparency rules took effect on August 2, 2026, including that users must be explicitly notified when interacting with AI (like customer service chatbots). Upcoming dates to note:
- December 2, 2027: Full compliance deadline for standalone AI systems in high-risk use cases (e.g., recruitment software, credit scoring tools).
- August 2, 2028: Full compliance deadline for AI embedded as safety components in regulated physical products (e.g., medical devices, aviation).
Dates are subject to change. For an up-to-date implementation timeline, visit the European Commission’s AI Act Service Desk.
What is "model drift" and how can you avoid it?
Model drift occurs when reality changes faster than an AI model can adapt. Due to model drift, the performance of even the most sophisticated chatbots tends to degrade over time. Models face three types of drift:
- Input drift: when the data your chatbot receives in production no longer resembles the data it was trained on. This can often happen when a new user segment is introduced, for example, if a retailer expands to a new geographic region.
- Label drift: When definitions of “right” and “wrong” shift, chatbots can experience label drift. If its responses are based on an outdated ground truth, the chatbot will come to false conclusions.
- Concept drift: when the underlying relationships and patterns the model learned start to change — either gradually or suddenly.
Continuous monitoring is one of the ways to ensure that your AI systems are still performing as intended.